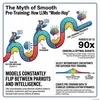
Generalization Dynamics of Language Model Pretraining
Large language models often exhibit unexpected behavioral fluctuations during pre-training, repeatedly shifting between memorizing shallow patterns and demonstrating true generalization, a phenomenon termed mode-hopping. This instability occurs independently of standard optimization metrics and persists even after training on trillions of tokens across various model scales. Consequently, tracking these hidden generalization dynamics using targeted evaluation suites enables researchers to identify superior intermediate checkpoints and strategically curate pre-training data to improve reasoning and alignment robustness.
Podzilla Summary coming soon
Sign up to get notified when the full AI-powered summary is ready.
Free forever for up to 3 podcasts. No credit card required.
Listen to This Episode
More from Best AI papers explained
Sparks of Weight-Space Programming: LLMs can natively read & write neural network weights
Quantifying Elicitation of Latent Capabilities in Language Models
The Trinity: Capability-Driven Recursive Self-Improvement for Multimodal Agents
High-Value Training Data from Noisy, Diverse Sources
Get summaries like this every morning.
Free AI-powered recaps of Best AI papers explained and your other favorite podcasts, delivered to your inbox.
Free forever for up to 3 podcasts. No credit card required.