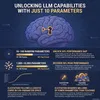
Quantifying Elicitation of Latent Capabilities in Language Models
This paper investigates how large language models unlock latent capabilities through fine-tuning, reframing the process as an information-constrained problem. By analyzing parameter-efficient fine-tuning using randomly chosen parameters, the authors demonstrate that training a tiny fraction of a model's weights—often as few as tens to thousands—can recover the vast majority of its full performance gap. This behavior follows a consistent logistic scaling relationship across various tasks, model sizes, and families, independent of specialized search methods. Furthermore, the study applies Rissanen's Minimum Description Length (MDL) principle to distinguish true capability elicitation from teaching new skills, offering insights that can improve capability forecasting and safety evaluations.
Podzilla Summary coming soon
Sign up to get notified when the full AI-powered summary is ready.
Free forever for up to 3 podcasts. No credit card required.
Listen to This Episode
More from Best AI papers explained
Against All Likelihood
Sample Complexity and Expressiveness of Test-Time Scaling Paradigms
H-Spec: Parallel Speculative Decoding Without a Drafter-Side KV Cache
Mass producing training data with surprising side effects
Get summaries like this every morning.
Free AI-powered recaps of Best AI papers explained and your other favorite podcasts, delivered to your inbox.
Free forever for up to 3 podcasts. No credit card required.