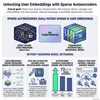
User Embeddings are Superpositions of Interpretable Behavioral Modes
This paper explores how sparse autoencoders can be applied to user embeddings to uncover hidden behavioral modes without needing raw interaction data or text-aligned training. By treating user representations as sparse superpositions of interpretable concepts, this post-hoc, model-agnostic framework enables zero-shot natural language audience retrieval and fine-grained characterization. Extensive validation on synthetic data, e-commerce records, and transformer-based sequential recommenders demonstrates that sparse autoencoders successfully recover underlying behavioral structures while outperforming classical dimensionality reduction methods in reconstruction fidelity, ranking quality, and feature diversity.
Podzilla Summary coming soon
Sign up to get notified when the full AI-powered summary is ready.
Free forever for up to 3 podcasts. No credit card required.
Listen to This Episode
More from Best AI papers explained
Against All Likelihood
Sample Complexity and Expressiveness of Test-Time Scaling Paradigms
H-Spec: Parallel Speculative Decoding Without a Drafter-Side KV Cache
Mass producing training data with surprising side effects
Get summaries like this every morning.
Free AI-powered recaps of Best AI papers explained and your other favorite podcasts, delivered to your inbox.
Free forever for up to 3 podcasts. No credit card required.